The Monk's Error, The Model's Echo
AI systems increasingly learn from text that earlier AI systems wrote. History has seen this error before, in monasteries.
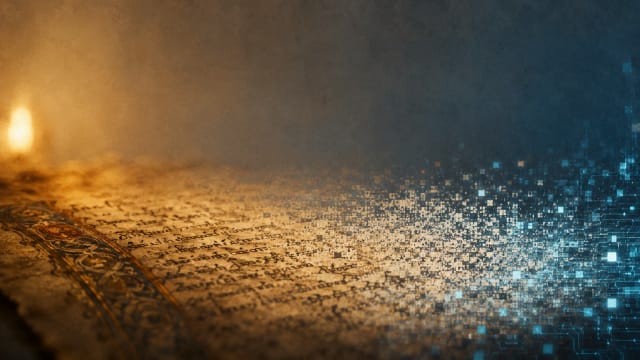
In the ninth century a monk in a scriptorium copies a manuscript by candlelight, and somewhere in the third chapter his hand slips, turning one word into another that sounds almost the same. The error is small enough to survive uncorrected, since no one thinks to check a text against a memory of a memory. Two centuries later a different monk copies that copy, and the slip is no longer a slip, it is simply what the text says, because no one alive has seen the original to correct it.
Something structurally similar is now happening at a speed no scriptorium ever managed. Large language models are trained on enormous samples of text drawn from the internet, and an increasing share of that text is itself generated by earlier language models rather than written by anyone at all. The next generation of systems is, in part, learning the world from the previous generation's guesses about the world.
Researchers have a name for the resulting drift, model collapse, the tendency for a system trained repeatedly on its own outputs to lose the rare, unusual, and statistically marginal information that made its training data resemble the actual richness of human experience. Each generation smooths slightly toward its own average, confident where it should be uncertain, until the tails of the distribution, the odd fact, the minority view, the exception that proved a rule, quietly go missing.
The next generation of systems is, in part, learning the world from the previous generation's guesses about the world.
It would be tempting to treat this as a novel danger unique to machines, but human culture has run versions of the same experiment for a long time. Oral traditions drift with each retelling. Newspapers cite other newspapers citing an original report that no living reporter can locate. Encyclopedias have occasionally been caught copying each other's errors so faithfully that a fabricated entry survived across editions for years, cited as though it were independent confirmation of itself.
The difference, if there is one, is not that machines recycle information while humans do not, but that human recycling has historically kept at least an intermittent tether to the world outside text, a traveler correcting a rumor, an experiment overturning a citation, a witness contradicting a legend. Language models, by contrast, encounter the world exclusively through text about the world, and as that text increasingly originates from other models rather than from perception, the tether loosens without anyone deciding to cut it.
What erodes first is not accuracy in any single fact but the internet's usefulness as a kind of ground truth, the background assumption that enough independent observers, writing independently, will collectively triangulate toward something real. When independence itself becomes uncertain, when a claim's frequency across the web may reflect how often a model repeated itself rather than how often reality was witnessed, verification stops being a matter of counting sources and becomes a much harder problem of tracing lineage.
Perhaps the more unsettling implication is how much of this predicament was already latent in human knowledge before any model existed. Most of what any person believes rests on testimony trusting other testimony, a chain few of us ever trace back to a direct encounter with the fact itself, whether the claim concerns a distant war, a historical date, or the safety of a medicine never personally tested. The scriptorium's error and the model's collapse are not aberrations in an otherwise clean system of knowing. They may simply be the moment the system's oldest vulnerability became visible enough, at last, to name.
Discussion · 1
The passage starts with a scenario of the monk copying a script and then another monk replicating the error of the first monk. The author then uses this scene to compare it with today's LLMs who are trained on previous LLMs. The author then discusses the problem with this and the danger of the model collapses. And then uses the model collapse to draw a parallel with human tendency and how humans have been doing this same thing since a long time and gives examples of it. But then the author also makes a distinction that even though both have the same tendency, humans are more tethered to reality because there will be tourists, scientists, experiments which will correct the divergence but how AI trained on previous models keep moving far from reality. And in this, accuracy is not the only thing we lose, but also the usefulness of the internet as a whole and then humans will have to verify it by tracing each claim back to its origin.
Sign in to join the discussion.
More in Artificial Intelligence
What the Algorithm Cannot Taste
Every major technology company is racing to quantify human experience. The one thing they cannot quantify is the reason the race matters.
The Loneliest Relationship Is Not With a Robot
Artificial companions do more than imitate intimacy. They expose the hidden assumptions that have always shaped how humans recognise love.
The Cloud Was Always a Factory
Artificial intelligence is reshaping the world, but hidden datacenters, rising energy use, and ecological costs reveal the true price of the AI revolution.
The Myth of the Human Artist
Why does AI art feel inhuman? A philosophical essay on creativity, technology, authenticity, and the shifting meaning of artistic expression.